Introduction
Here is a small experiment that surprises almost everyone the first time they see it.
Take a query vector q = [1, 0] and two candidate vectors:
a = [10, 0]b = [0.5, 0.5]
Cosine similarity says a is a perfect match (cos = 1.0) and b is merely decent (cos ≈ 0.707). Euclidean distance says the opposite: b is the closer neighbor (0.707) while a sits nine units away.
Same vectors, same arithmetic, two contradictory rankings. Neither metric is wrong. They are answering different questions, and the gap between those questions is where a great deal of Data Science quietly goes wrong.
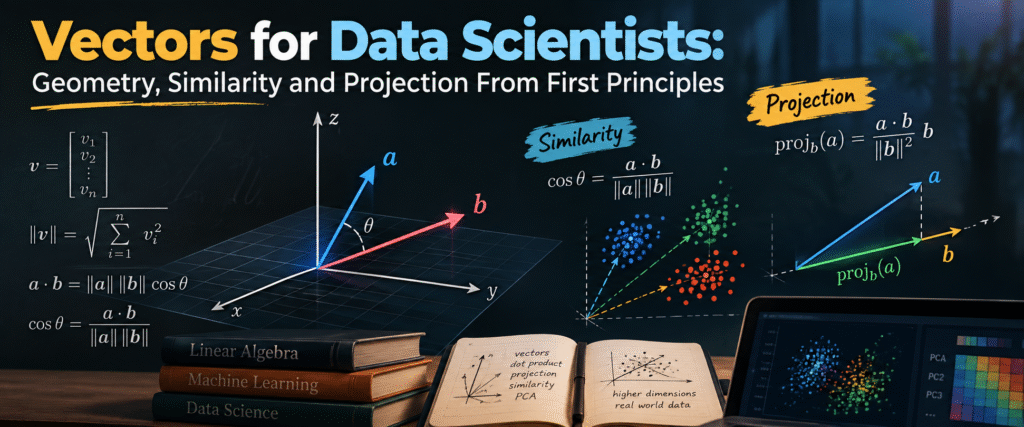
The uncomfortable truth is that “a vector” is not a list of numbers. It is a list of numbers plus a geometry — an inner product that defines length, angle, distance and projection. Choose the inner product carelessly and you have chosen your model’s conclusions before it ever sees the data.
By the end of this article you should be able to: explain what a vector space really assumes; derive cosine similarity from the Cauchy–Schwartz inequality rather than memorising it; understand projection as the “best approximation” theorem that secretly is linear regression and PCA; implement all of it in NumPy and scikit-learn; and know exactly which failure modes to expect in high dimensions.
Why This Matters
Almost every modern ML pipeline reduces to three operations on vectors: compare them, combine them, or project them onto something smaller.
- Comparing: nearest-neighbor search, retrieval, deduplication, recommendations, embedding evaluation.
- Combining: attention in transformers, weighted ensembles, linear layers.
- Projecting: PCA, regression, factor models, low-rank compression.
Get the geometry wrong and the failure is silent. A recommender that ranks by raw dot product will recommend whatever is popular. A retrieval system that “accidentally” normalises along the wrong axis will still return results — just bad ones. A text pipeline that uses cosine similarity but forgets that its embeddings are anisotropic will report that every document is moderately similar to every other document.
The cost of these mistakes is not a crash. It is a plausible-looking number that happens to be meaningless. That is the worst kind of bug, and it is why the linear algebra deserves a proper treatment rather than a pip install and a shrug.
Prerequisites
You need less than you think:
- Comfort with Python and NumPy arrays (
shape,@, broadcasting). - High-school trigonometry plus the idea of a summation.
- Basic probability (expectation, variance) for the concentration argument at the end.
- Ideally some exposure to Matrix Multiplication as Composition of Linear Maps.
Nothing here requires measure theory, differential geometry, or a course in functional analysis. The mathematics is genuinely elementary. What is not elementary is knowing why each object exists.
Intuition Before Formalism
A vector is an arrow: a direction and a length. When we treat a row of a dataframe as a vector, we are asserting something strong — that the feature columns are coordinates in a shared space, and that the resulting arrow has a meaningful direction.
Consider a document represented by term frequencies. Its “direction” says something about what it is about; its “length” says something about how long it is. For topical similarity, length is noise, so we discard it — that is exactly what cosine similarity does. For measuring engagement, intensity, or popularity, length may be the entire signal, and discarding it would be an unforced error.
This gives the first useful heuristic of the whole subject:
Cosine similarity answers “what direction is this pointing?” Euclidean distance answers “how close is this point?” Dot product answers “how much of one is in the other?”
A useful thought experiment: imagine a city map where north–south streets count double, because you decided distance should emphasise latitude. Valid construction. Also now your “circle” is an ellipse, your projections are skewed, and nothing behaves the way you learned. That arbitrary reweighting is precisely what standardising features, duplicating a feature column, or applying a Mahalanobis transform does. Geometry is a choice.
There is a rock-and-roll version of the same point. In This Is Spinal Tap, Nigel Tufnel’s amplifier is special because “these go to eleven” — the numbers changed, and with them everything downstream. Multiply one feature by ten and your norms, angles and nearest neighbours all change, even though “the data” did not. There is no canonical scale. There is only the one you chose, for reasons you should be able to state out loud.
Mathematical Foundation
1. What a vector space actually asserts
A real vector space V is a set with two operations — addition and scalar multiplication — satisfying the usual eight axioms (associativity, commutativity, identity, inverses, distributivity). Those axioms are unglamorous, but they buy three things we rely on constantly: we can form linear combinations freely, the span of a set of vectors is itself a subspace, and any maximal linearly independent set is a basis of size dim(V).
Two consequences matter for practice. First, coordinates are a representation, not the object. The vector [3, 4] is not “3 and 4”; it is an arrow whose coordinates in a particular basis are 3 and 4. Change the basis and the numbers change while the arrow does not. Second, dimension is a property of the space, not of the sample. A dataset with 10 rows and 500 columns lives in R⁵⁰⁰, no matter how few points you have. Much of the pathology in Section “What Happens If” flows from that asymmetry.
2. Inner products create geometry
A vector space alone has no notion of length or angle. That structure comes from an inner product: a map ⟨·,·⟩ : V × V → R that is symmetric, bilinear, and positive definite (⟨x, x⟩ ≥ 0, with equality only if x = 0).
On Rᵈ the standard example is
⟨x, y⟩ = xᵀy = Σᵢ xᵢ yᵢ
with the induced norm ‖x‖ = √⟨x, x⟩. Positive definiteness is the load-bearing axiom: it is what guarantees ‖x‖ = 0 implies x = 0, and therefore that distance d(x, y) = ‖x − y‖ really is a metric.
The moment you swap the standard inner product for something like ⟨x, y⟩M = xᵀ M y with M positive definite, you get a different geometry — different lengths, different angles, different “nearest neighbours”. This is not an abstraction: Mahalanobis distance is exactly ⟨x, y⟩{Σ⁻¹}, and its entire purpose is to correct for correlated features.
Orthogonality is defined by the inner product: x ⊥ y iff ⟨x, y⟩ = 0. This definition is doing more work than it appears to. It means orthogonality is a consequence of your chosen geometry, not an absolute fact about the numbers.
3. Cauchy–Schwartz, and why cosine similarity exists
Dividing one vector by its norm maps it onto the unit sphere. The interesting question is: how far can two unit vectors go? The answer is the Cauchy–Schwartz inequality, and it is worth deriving because the derivation tells you why the formula is forced rather than invented.
Take any real t. Positive definiteness gives
0 ≤ ‖x − t y‖² = ‖x‖² − 2t⟨x, y⟩ + t²‖y‖²
The right-hand side is a convex quadratic in t, so minimising it over t is legitimate. Differentiate and set to zero:
−2⟨x, y⟩ + 2t‖y‖² = 0 ⟹ t* = ⟨x, y⟩ / ‖y‖²
Substituting t* back:
0 ≤ ‖x‖² − ⟨x, y⟩² / ‖y‖²
⟹ ⟨x, y⟩² ≤ ‖x‖² ‖y‖²
⟹ |⟨x, y⟩| ≤ ‖x‖ ‖y‖
For nonzero vectors this says
−1 ≤ ⟨x, y⟩ / (‖x‖ ‖y‖) ≤ 1
which is precisely the range of cos θ. We may therefore define
cosine_similarity(x, y) = ⟨x, y⟩ / (‖x‖ ‖y‖)
and know that it is a legitimate angular quantity, not an ad hoc rescaling. Note the practical corollary: cosine similarity is bounded only because the inner product is positive definite. Swap in an indefinite bilinear form and the “similarity” can exceed 1 — a bug that shows up in attention variants and in kernel tinkering.
Three invariances follow immediately:
- Invariant to rotation and reflection. If QᵀQ = I, then ⟨Qx, Qy⟩ = xᵀQᵀQy = ⟨x, y⟩. Cosine similarity cannot see rotations. This is why random projection works at all.
- Invariant to per-vector scaling. x → c x with c > 0 leaves the cosine unchanged.
- Not invariant to per-dimension scaling. Rescaling feature j changes everything. This is the single most common source of “why did my similarity change when I only standardised the data?”
4. Cosine similarity is Pearson correlation on centred vectors
Centre each vector by subtracting its mean across dimensions, x̃ = x − x̄·1. Then
cosine(x̃, ỹ) = Σᵢ (xᵢ − x̄)(yᵢ − ȳ) / √(Σ(xᵢ − x̄)² Σ(yᵢ − ȳ)²)
which is exactly the Pearson correlation coefficient. So correlation is not a mysterious separate statistic; it is cosine on mean-centred data. This is why running cosine similarity without centring on data where the mean matters (raw word counts, uncentred embeddings) gives answers that look surprisingly uniform and large.
5. Projection: the best approximation theorem
The projection of x onto a subspace S is the unique point p ∈ S minimising ‖x − p‖. That is the definition, not a formula. It follows from the closest-point property that the residual x − p is orthogonal to every vector in S.
Now make it concrete. Let the columns of U ∈ R^{d×k} form an orthonormal basis of S, so UᵀU = I_k, and let p = U c. Minimise:
‖x − Uc‖² = ‖x‖² − 2cᵀUᵀx + cᵀUᵀUc
           = ‖x‖² − 2cᵀUᵀx + cᵀc
Differentiate with respect to c and set to zero:
−2Uᵀx + 2c = 0 ⟹ c = Uᵀx
So p = U Uᵀ x, and the projection matrix is
P = U Uᵀ, with P² = P and Pᵀ = P
The idempotence P² = P is the algebraic signature of “projecting twice changes nothing”, and symmetry is the signature of orthogonal (rather than oblique) projection. For a general basis B with full column rank, the same argument gives the normal equations P = B(BᵀB)⁻¹Bᵀ.
Now notice what you have just written. Substitute B for the design matrix X and y for x:
ŷ = X(XᵀX)⁻¹Xᵀ y
That is ordinary least squares. Regression is not “like” projection; regression is projection of the response onto the column space of the predictors. The Gauss–Markov theorem is a statement about the geometry of that projection. If you understood the derivation above, you already understand why the residual vector is orthogonal to every predictor — and why adding a predictor that is a linear combination of existing ones gives XᵀX singular.
6. Gram matrices and the full similarity picture
If the rows of X ∈ R^{n×d} are your data vectors, the Gram matrix is
G = X Xᵀ ∈ R^{n×n}, G_ij = ⟨xᵢ, xⱼ⟩
Everything you want to know about pairwise relationships lives in G or in matrices derived from it. The cosine similarity matrix is the normalised Gram matrix:
S = D⁻¹ G D⁻¹, D = diag(‖x₁‖, …, ‖xₙ‖)
The scatter matrix XᵀX (d × d) is a different object with a different job: its eigenvectors are the principal directions. The Gram matrix and the scatter matrix share nonzero eigenvalues — a duality worth internalising, because it means you can do PCA through whichever of the two is smaller.
7. From projection to PCA
Let S denote the centred scatter matrix X̃ᵀX̃. The eigendecomposition S = V Λ Vᵀ gives the principal directions as the columns of V, ordered by the eigenvalues λ₁ ≥ λ₂ ≥ …
The top-k principal subspace is spanned by the first k columns of V. Projecting onto it, per the derivation above, yields the reconstruction
x̂ = V_k V_kᵀ x̃
The Eckart–Young–Mirsky theorem guarantees that this is the optimal rank-k approximation of X̃ in both Frobenius and spectral norm. The unexplained energy is exactly Σ_{j>k} λⱼ, which is why a scree plot is a legitimate accounting device and not a heuristic ritual. So PCA is not a separate topic from vector projection. It is the best-approximation theorem with an eigenvalue problem attached.
The Chain From Mathematics to Data Science
Inner product → norm and angle → cosine similarity → TF-IDF retrieval → vector databases and RAG. The vector space model for information retrieval is due to Salton, Wong and Yang (1975); the machinery is unchanged in a modern embedding index. Only the vectors got denser.
Inner product → Gram matrix → kernel functions → SVM and Gaussian processes. A kernel is just an inner product in a feature space you never materialise. The kernel trick works because every algorithm you care about can be written using only ⟨xᵢ, xⱼ⟩.
Projection → normal equations → least squares → ridge regression. The ridge solution β = (XᵀX + λI)⁻¹Xᵀy is a projection onto a shrunk subspace; the L2 penalty pulls the estimate toward the origin, and the geometry of that pull is why ridge coefficients never hit exactly zero while Lasso’s do.
Projection → Eckart–Young → PCA → whitening → Mahalanobis distance. Whitening is projection onto the principal axes followed by rescaling to unit variance. It converts the standard inner product into the Σ⁻¹ inner product.
Dot product → softmax → attention. Scaled dot-product attention (Vaswani et al., 2017) computes softmax(QKᵀ/√dk)V. The √dk divisor is not folklore: if the components of q and k are independent with variance 1, then ⟨q, k⟩ has variance dk, so the logits grow like √dk. Without rescaling, softmax saturates and gradients vanish. The scaling is a variance normalisation derived directly from the inner product.
Dot product → ranking → approximate nearest neighbor. FAISS, HNSW, ScaNN and friends index either L2 or inner product. Cosine similarity is not directly indexable in an inner-product index; you normalise first, then inner product and cosine coincide. Forgetting this step is a classic production bug.
Python Implementation
From scratch
import numpy as np

def cosine_similarity(x, y):
    """Cosine similarity with explicit zero-vector handling."""
    x = np.asarray(x, dtype=float)
    y = np.asarray(y, dtype=float)
    denom = np.linalg.norm(x) * np.linalg.norm(y)
    if denom == 0.0:
        return np.nan  # undefined; do not silently return 0
    return float(x @ y / denom)


def cosine_similarity_matrix(X):
    """All-pairs cosine similarity for rows of X."""
    X = np.asarray(X, dtype=float)
    norms = np.linalg.norm(X, axis=1, keepdims=True)
    norms = np.where(norms == 0.0, 1.0, norms)  # zero rows stay zero rows
    Xn = X / norms
    return Xn @ Xn.T
The axis=1 in np.linalg.norm is the entire ballgame. Using axis=0 computes per-column norms, which is dimensionally consistent, runs without error, and produces garbage. It is worth writing a unit test that asserts each returned row has norm 1 (for nonzero inputs) just to make the bug impossible.
Projection, from scratch and via lstsq
def projector(B):
    """Orthogonal projection matrix onto span(columns of B), via QR."""
    Q, R = np.linalg.qr(B)
    return Q @ Q.T


def project(x, B):
    """Project x onto span(columns of B)."""
    # lstsq solves the same least-squares problem more robustly
    coeffs, *_ = np.linalg.lstsq(B, x, rcond=None)
    return B @ coeffs
lstsq is preferred in practice over forming B (BᵀB)⁻¹ Bᵀ explicitly: squaring the condition number by forming BᵀB is a genuinely bad idea when B is ill-conditioned, and lstsq uses a QR or SVD route that avoids it.
The library version
from sklearn.metrics.pairwise import cosine_similarity
from sklearn.preprocessing import normalize

X = np.random.default_rng(0).standard_normal((50, 8))
S_scratch = cosine_similarity_matrix(X)
S_sklearn = cosine_similarity(X)

assert np.allclose(S_scratch, S_sklearn)          # same matrix, same convention
assert np.allclose(normalize(X) @ normalize(X).T, S_sklearn)
The last line is the practical identity worth remembering: cosine similarity between rows equals the inner product of L2-normalised rows. In production retrieval systems, that is the only form you ever compute, because it is the form that maps onto a matrix multiply and therefore onto hardware.
A TF-IDF sanity check
from sklearn.feature_extraction.text import TfidfVectorizer
from sklearn.metrics.pairwise import cosine_similarity

docs = [
    "the market discounted the rate cut before it was announced",
    "bond prices rallied as traders priced in an earlier cut",
    "the central bank held rates steady and signalled patience",
    "my sourdough starter finally doubled in size",
]

vectorizer = TfidfVectorizer(stop_words="english")
X = vectorizer.fit_transform(docs)
S = cosine_similarity(X)

for i in range(len(docs)):
    for j in range(i + 1, len(docs)):
        print(i, j, round(S[i, j], 3))
Expected qualitative behaviour: documents 0 and 1 should be the most similar pair, sharing the token “cut”; document 3, the sourdough, should be the least similar to everything. One caveat that is itself instructive: TfidfVectorizer does not stem by default, so “rate” (doc 0) and “rates” (doc 2) are different dimensions. Your tokenisation is your geometry. Change the analyser and the neighbourhoods change.
Experiment: Does Cosine Similarity Lose Its Meaning in High Dimensions?
Hypothesis
For independent random vectors with i.i.d. standard normal coordinates, the pairwise cosine similarity concentrates around 0, with standard deviation shrinking as 1/√d. In high dimensions, everything becomes almost orthogonal to everything else — so a cosine of 0.05 at d = 1000 is unremarkable, not evidence of relatedness.
Method
Sample n = 500 vectors at several dimensions, compute the full cosine similarity matrix, and examine the off-diagonal distribution. Compare the empirical spread to the theoretical value.
The theory here is exact rather than asymptotic, which makes this a clean test. For two independent standard Gaussian vectors x, y ∈ Rᵈ, the common direction is uniform on the sphere and independent of the radius, so cos(x, y) has the same law as the cosine between two independent uniform random directions. Its density on (−1, 1) is proportional to (1 − c²)^{(d−3)/2}, symmetric about zero, and
E[cos] = 0
Var[cos] = 1 / d     ⟹     sd = 1 / √d
Code
import numpy as np
import pandas as pd
import matplotlib.pyplot as plt

rng = np.random.default_rng(0)


def off_diagonal_cosines(X):
    Xn = X / np.linalg.norm(X, axis=1, keepdims=True)
    S = Xn @ Xn.T
    iu = np.triu_indices_from(S, k=1)
    return S[iu]


rows = []
for d in [2, 10, 100, 1000, 10000]:
    X = rng.standard_normal((500, d))
    c = off_diagonal_cosines(X)
    rows.append({
        "d": d,
        "mean": c.mean(),
        "sd": c.std(ddof=1),
        "1/sqrt(d)": 1 / np.sqrt(d),
        "p95_abs": np.quantile(np.abs(c), 0.95),
        "max_abs": np.abs(c).max(),
    })

print(pd.DataFrame(rows).round(5).to_string(index=False))

# Visual: the distribution collapses as dimension grows
fig, ax = plt.subplots(figsize=(8, 5))
for d, color in [(2, "steelblue"), (10, "darkorange"), (1000, "firebrick")]:
    c = off_diagonal_cosines(rng.standard_normal((500, d)))
    ax.hist(c, bins=80, density=True, histtype="step", linewidth=2,
            color=color, label=f"d = {d}")
ax.set_xlabel("pairwise cosine similarity")
ax.set_ylabel("density")
ax.set_title("Concentration of cosine similarity with dimension")
ax.legend()
plt.tight_layout()
plt.show()
Result
The table below gives the analytically predicted standard deviation, not a recorded run. I did not execute this snippet while writing; the values are derived from Var[cos] = 1/d, which is exact for independent Gaussian vectors.
| d | predicted sd = 1/√d | predicted 95th percentile of cos |
|---|---|---|
| 2 | 0.70711 | ≈ 0.975 (arcsine-like, heavy tails) |
| 10 | 0.31623 | ≈ 0.52 |
| 100 | 0.10000 | ≈ 0.165 |
| 1,000 | 0.03162 | ≈ 0.052 |
| 10,000 | 0.01000 | ≈ 0.016 |
Running the code should reproduce these to within Monte Carlo error (with 500 vectors there are 124,750 pairs, so the standard error on the mean is small; the sample sd should sit close to 1/√d). The mean should be indistinguishable from zero in every case. If you obtain a mean far from zero, you have a bug in the normalisation — axis=0 is the usual suspect.
Interpretation
Three practical consequences follow.
First, thresholds must scale with dimension. A fixed cutoff like “similarity > 0.8 means duplicate” is defensible for a 50-dimensional TF-IDF space and useless in a 1536-dimensional embedding space, where 0.8 may be several standard deviations above chance for some vector pairs and entirely routine for others. Calibrate thresholds against the empirical null distribution of your vectors, not against a rule of thumb copied from a blog post.
Second, the geometry of random high-dimensional data is counterintuitive in both directions. Chebyshev’s inequality gives P(|cos| > k/√d) ≤ 1/k², so large deviations from orthogonality are rare, yet with n vectors you compute O(n²) pairs, and the maximum will be much larger than the typical value. With a million documents, someone in your corpus will have a spurious cosine of 0.3 by chance alone. This is why approximate nearest neighbor indexes need careful calibration of the search radius, and why “I found a match at 0.31” is not evidence of anything.
Third, real embeddings are nothing like the null model. They are anisotropic: they occupy a narrow cone rather than the whole sphere, so all pairwise cosines are large and positive. Research on this (Ethayarajh, 2019; Mu and Viswanath, 2018) found that subtracting the mean vector and removing the top few principal components substantially improves the usefulness of cosine comparisons in contextual embedding spaces. The null model above is the baseline you compare against; it tells you what “structureless” looks like, and it is not the same in every dimension.
Assumptions
1. The features form a meaningful Euclidean space. Cosine similarity and Euclidean distance both assume coordinates live on a common scale grid. Standardising features, log-transforming counts, or duplicating a column all redefine that space. This is not a violation to be tolerated; it is a modelling decision that must be made consciously.
2. For cosine, direction is the signal and magnitude is noise. This is a semantic assumption, not a mathematical one. It is well justified for term-frequency vectors of unequal length, where length encodes verbosity. It is actively harmful when magnitude encodes confidence, quantity, popularity or severity.
3. For Euclidean, features are on comparable scales and not strongly collinear. Correlated features are effectively counted twice, so Euclidean distance over-weights whichever direction the correlation lies in. Mild collinearity is tolerable; severe collinearity deserves whitening, which converts Euclidean distance into Mahalanobis distance.
4. For projection methods, the structure of interest is linear. PCA finds the best linear subspace. If your data lives on a curved manifold — a common situation for images and graphs — the linear projection is an approximation whose error depends on curvature, and nonlinear methods may be warranted.
5. For TF-IDF cosine specifically, tokens are conditionally independent given the document. The bag-of-words model ignores word order entirely. This is a strong and usually false assumption that nevertheless works well for topical similarity, which is a good reminder that useful assumptions need not be true, only not too damaging.
Pitfalls and Failure Modes
Mathematical misconceptions
“Cosine similarity is a metric.” It is not. 1 − cos(x, y) violates the triangle inequality. The angular distance θ = arccos(cos) is a genuine metric on the unit sphere, and so is the chord distance ‖x̂ − ŷ‖. If you are feeding a distance into an algorithm that assumes the triangle inequality — a metric tree, a cover-tree index, DBSCAN with metric="precomputed" — decide carefully which of the three you mean. They rank identically but bound differently.
“Orthogonal means unrelated.” Orthogonality means uncorrelated only in the centred inner product. Two raw count vectors can have a zero inner product because they share no vocabulary, which is informative; they can also have a zero inner product because one is centred and the other is not, which is an artefact.
“Cosine handles scale automatically, so preprocessing is unnecessary.” Cosine is invariant to per-vector scaling but not to per-dimension scaling. Changing the units of one column changes every angle in the dataset.
Implementation mistakes
The axis bug. Covered above, and it is the most common one. Assert your invariants.
Division by zero on empty rows. A document with no in-vocabulary terms produces a zero vector. NumPy division yields nan; scikit-learn’s normalize leaves zeros as zeros. The two behaviours propagate differently, and nan silently poisons every downstream aggregate.
Normalising at the wrong time. If you centre and then normalise, you get cosine on centred vectors, which is correlation. If you normalise and then centre, you get something else. Both are computable; only one matches what you meant.
Index–query mismatch in ANN search. Building an inner-product index (FAISS IndexFlatIP) and querying with unnormalised vectors gives magnitude-dominated results. Building an L2 index and querying normalised vectors gives, by the earlier identity ‖a − b‖² = 2 − 2⟨a, b⟩, results that rank identically to cosine. Mixing the two conventions is a silent accuracy killer.
Float32 precision. At 1536 dimensions, float32 accumulation error in a dot product is non-trivial. If two candidates have cosines of 0.81204 and 0.81207, the ranking may not survive a type conversion. When ties matter — deduplication, top-k with a cutoff — accumulate in float64.
Statistical mistakes
Vectoriser leakage. Fitting TfidfVectorizer on the full corpus before splitting means the IDF weights have seen the test set. The leak is usually mild, but it is free to avoid: fit on train, transform on test.
Evaluating embeddings with cosine on a null-calibrated scale. As the concentration result shows, an absolute similarity threshold is not portable across embedding spaces. Report rank-based metrics, or calibrate against the empirical null.
Hubness. In high-dimensional spaces, some points appear as the nearest neighbor of a disproportionate number of other points. This is a documented phenomenon (Radovanović, Nanopoulos and Ivanović, 2010) and it degrades kNN classifiers, recommendation and retrieval alike. It is not a bug in your code — it is a property of the geometry.
Production failure modes
Dense materialisation of the similarity matrix. For n = 10⁶ documents, the full Gram matrix is 10¹² entries. Nobody needs it. Use blocked computation, sparse formats, or an ANN index — and if you genuinely need exact all-pairs at that scale, reconsider the requirement.
Spherical k-means confusion. Running k-means on cosine normalised vectors is not the same as spherical k-means, which constrains centroids to the unit sphere. Standard k-means on L2-normalised vectors is a common approximation and it usually behaves acceptably, but the objective is different and the convergence guarantees do not transfer. scikit-learn’s KMeans optimises squared Euclidean distance; if that is not your objective, say so explicitly.
Uncentred embeddings drifting over time. Retraining an embedding model shifts the mean vector. Any pipeline with an implicit mean-centring step (including “all-but-the-top” post-processing) will silently change its behaviour on upgrade. Version your preprocessing alongside your model.
What Happens If… (Edge-Case Analysis)
…the vectors are not unit length and you use a dot-product index? Popularity wins. The highest-norm vectors dominate every ranking. This is the mathematically precise version of “the recommender only recommends bestsellers.”
…dimension exceeds the number of samples? d > n means the data lies in an affine subspace of dimension at most n − 1, the scatter matrix is singular, and PCA has d − n + 1 exact zero eigenvalues. Projecting onto those directions is fitting noise. Always regularise or restrict to k < n.
…features are duplicated? Cosine similarity is not invariant to duplicating a column. The duplicated dimension gets double weight in the inner product but only √2 times the weight in the norm. The cosine changes, and it changes non-uniformly across pairs: pairs differing mainly in that dimension are pushed closer, others farther.
…the data is standardised after computing similarities? You have two incompatible geometries in one pipeline. Symptom: similarity rankings that contradict the model’s predictions, with no code error visible.
…the matrix is ill-conditioned? Forming B(BᵀB)⁻¹Bᵀ squares the condition number of B. At κ(B) = 10⁸ in float64 you lose roughly half your significant digits to the explicit inverse alone. Use QR or SVD.
…you mix L1 and L2 norms? They are different geometries. normalize(X, norm="l1") puts rows on a simplex; norm="l2" puts them on a sphere. Both are valid; only one is compatible with a dot-product index.
…distributions are heavy-tailed? In a heavy-tailed null distribution, rare co-occurrences produce extreme similarity values. A single shared rare token can dominate a TF-IDF cosine. Sublinear TF scaling and IDF weighting exist precisely to mitigate this, and they are not universal cures.
When to Use Cosine Similarity
- Text and sparse high-dimensional count vectors, where document length is a nuisance parameter.
- Dense embeddings, provided you have checked for anisotropy and calibrated any thresholds.
- Retrieval and recommendation where topical direction matters more than intensity.
- Deduplication of near-identical documents, in combination with a rank-based or empirically calibrated cutoff.
- Cross-lingual or cross-modal matching, where lengths are not comparable but directions may be.
When Not to Use Cosine Similarity
- When magnitude carries semantic information: engagement counts, prices, severity scores, confidence estimates.
- When your vectors are all non-negative and sparsely populated and you care about co-occurrence counts rather than angles — a Jaccard or overlap coefficient may be more interpretable.
- When your features are highly correlated and you have not whitened. Mahalanobis distance is the principled alternative.
- When the algorithm requires a true metric and you need triangle-inequality bounds; use angular or chord distance instead.
- When you are computing distances for clustering with algorithms that assume Euclidean geometry (Gaussian mixture models, standard k-means) without adjusting the objective.
Comparison With Alternatives
| Property | Dot product | Euclidean | Cosine | Jaccard | Mahalanobis |
|---|---|---|---|---|---|
| Definition | ⟨x, y⟩ | ‖x − y‖ | ⟨x, y⟩/(‖x‖‖y‖) | A∩B | |
| Invariant to rotation | Yes | Yes | Yes | N/A (set-based) | Yes |
| Invariant to per-vector scaling | No | No | Yes (positive scale) | N/A | No |
| Sensitive to magnitude | Strongly | Yes | No | No | Yes |
| Corrects for correlated features | No | No | No | No | Yes |
| Is a metric | No | Yes | No (see angular/chord distance) | Yes (on sets) | Yes |
| Typical use | Attention; ANN on unit vectors | Dense numeric features; k-means | Text; embeddings | Binary sets; bag-of-tokens | Correlated multivariate data |
| Main caveat | Popularity dominates | Scale and correlation dependent | Discards magnitude; hubness | Ignores counts | Needs invertible Σ (or pseudo-inverse) |
Two rows deserve a note. The dot product’s “not a metric” entry is not a technicality: it is why inner-product indexes require normalised vectors for cosine behaviour. And Mahalanobis distance is not a different universe — it is Euclidean distance in a whitened coordinate system, which is the point.
Key Takeaways
A vector is numbers plus an inner product. Change the inner product and you change every angle, distance and neighbor. Data can be summarised; a geometry cannot be neutral.
Cosine similarity is Cauchy–Schwartz made practical. The bound |⟨x, y⟩| ≤ ‖x‖‖y‖ guarantees the normalised inner product lies in [−1, 1], which is why the ratio is a legitimate angular measure rather than a convenient hack.
Projection is the best-approximation theorem, and it is everywhere. Regression, PCA, whitening and low-rank compression are all the same derivation with different matrices plugged in. Understanding the normal equations once pays for itself repeatedly.
In high dimensions, orthogonality is the default, not an anomaly. Var[cos] = 1/d exactly for independent Gaussian vectors. Any absolute similarity threshold that ignores the ambient dimension is a liability.
The most common failure is silent, not loud. The
axis=0normalisation bug, the inner-product index fed unnormalised vectors, and the similarity computed on uncentred data all run to completion and return plausible numbers. Invariant checks are not paranoia; they are the job.Choose the metric before you choose the model. Metric choice precedes architecture. It encodes what “similar” means for your problem, and no amount of hyperparameter tuning recovers from getting it wrong.
Practical Next Steps
- Reproduce the concentration experiment. Run the snippet, then extend it to non-Gaussian coordinates (uniform, heavy-tailed, sparse binary) and see how the variance of cosine deviates from 1/d. Sparse binary vectors behave very differently, and the reason is worth understanding.
- Write the invariant tests. For any similarity function you ship, assert symmetry, self-similarity equal to one for nonzero vectors, and the identity between cosine and inner product on normalised rows.
- Break it deliberately. Duplicate a feature column, rescale one dimension by 100, and re-run a kNN classification. Observe how the accuracy moves. This builds intuition for scale sensitivity faster than any proof.
- Derive the ridge geometry. Show that ridge regression corresponds to projecting y onto the column space of an augmented matrix [X; √λ I]. It is a two-line argument and it explains shrinkage visually.
- Read the primary sources. Salton, Wong and Yang (1975) for the vector space model; Eckart and Young (1936) for the low-rank optimality theorem; Johnson and Lindenstrauss (1984) for why random projection preserves distances.
Mini-Project
Objective
Build a small retrieval system with two interchangeable similarity backends — exact cosine on normalised vectors and an approximate inner-product index — and quantify where the approximation diverges from the exact ranking.
Dataset
Any public text corpus. A standard evaluation collection such as the scikit-learn 20newsgroups dataset is convenient and reproducible; a synthetic corpus of 10,000 documents from 20 topics works equally well if you prefer full control. Here is a notebook on topic modeling using LSA and LDA.
Tasks
- Build TF-IDF features with
TfidfVectorizer, fitting only on the training split. Confirm all rows have unit L2 norm. - Implement an exact top-k retrieval function with NumPy, returning rank and score for 200 held-out queries.
- Replace the backend with an approximate nearest neighbor index (FAISS or scikit-learn’s
NearestNeighborswithmetric="cosine"), then with an inner-product index on the same normalised vectors. - Measure recall@k and mean reciprocal rank across the three backends, and record query latency.
- Repeat step 4 after removing the normalisation step, and record what breaks.
Questions to Investigate
- At what corpus size does the approximate index’s recall@10 drop below 0.9 for your data, and does that threshold depend on the intrinsic dimensionality rather than n?
- Removing normalisation changes the inner-product backend’s rankings substantially but leaves the exact cosine backend unchanged. Explain algebraically why, and identify which document lengths are most affected.
- Compute the mean of all off-diagonal cosine similarities in your corpus. If it is far from zero, what does that tell you about the geometry of TF-IDF vectors, and how would the concentration experiment’s null model need to be adapted?
References
- Salton, G., Wong, A., and Yang, C. S. (1975). “A Vector Space Model for Automatic Indexing.” Communications of the ACM, 18(11), 613–620.
- Manning, C. D., Raghavan, P., and Schütze, H. (2008). Introduction to Information Retrieval. Cambridge University Press. Chapter 6, “Scoring, term weighting and the vector space model.”
- Strang, G. (2019). Linear Algebra and Learning from Data. Wellesley–Cambridge Press.
- Hastie, T., Tibshirani, R., and Friedman, J. (2009). The Elements of Statistical Learning, 2nd ed. Springer. Chapter 3 (least squares geometry) and Section 14.5 (PCA and the Eckart–Young theorem).
- Eckart, C., and Young, G. (1936). “The approximation of one matrix by another of lower rank.” Psychometrika, 1(3), 211–218.
- Johnson, W. B., and Lindenstrauss, J. (1984). “Extensions of Lipschitz mappings into a Hilbert space.” Contemporary Mathematics, 26, 189–206.
- Vaswani, A., et al. (2017). “Attention Is All You Need.” Advances in Neural Information Processing Systems 30. arXiv:1706.03762.
- Mikolov, T., Chen, K., Corrado, G., and Dean, J. (2013). “Efficient Estimation of Word Representations in Vector Space.” arXiv:1301.3781.
- Pennington, J., Socher, R., and Manning, C. D. (2014). “GloVe: Global Vectors for Word Representation.” Proceedings of EMNLP 2014.
- Mu, J., and Viswanath, P. (2018). “All-but-the-Top: Simple and Effective Postprocessing for Word Representations.” International Conference on Learning Representations (ICLR).
- Ethayarajh, K. (2019). “How Contextual are Contextualized Word Representations? Comparing the Geometry of BERT, ELMo, and GPT-2 Embeddings.” Proceedings of EMNLP-IJCNLP 2019.
- Radovanović, M., Nanopoulos, A., and Ivanović, M. (2010). “Hubs in Space: Popular Nearest Neighbors in High-Dimensional Data.” Journal of Machine Learning Research, 11, 2487–2531.
- Aggarwal, C. C., Hinneburg, A., and Keim, D. A. (2001). “On the Surprising Behavior of Distance Metrics in High Dimensional Space.” ICDT 2001.
- Beyer, K., Goldstein, J., Ramakrishnan, R., and Shaft, U. (1999). “When Is ‘Nearest Neighbor’ Meaningful?” ICDT 1999.
- scikit-learn developers. “
sklearn.metrics.pairwise.cosine_similarity,” “sklearn.preprocessing.normalize,” “sklearn.neighbors.NearestNeighbors.” Official documentation. - NumPy developers. “
numpy.linalg.norm,” “numpy.linalg.lstsq,” “numpy.linalg.qr.” Official documentation. - FAISS documentation, Meta AI Research. “Index types and metric selection.”
FAQ
Is cosine similarity always between 0 and 1?
No. It ranges over [−1, 1]. It is confined to [0, 1] only when all vector components are non-negative — the usual case for term frequencies and TF-IDF, but not for centred data, embeddings with negative coordinates, or residual vectors. A negative cosine means the arrows point in opposing directions, which is meaningful information you should not clamp away.
Should I normalise before or after centring?
Decide from the semantics. If magnitude is noise and you want to compare compositions, normalise first (or use cosine directly). If you want correlation, centre first and then normalise — that is literally what Pearson correlation computes. Doing both in the wrong order produces a hybrid that is hard to interpret and easy to misdiagnose.
Why is my cosine similarity 0.99 for every pair of embeddings?
Almost certainly anisotropy. Embedding spaces are typically concentrated in a narrow cone, so all cosines are high. Common fixes: subtract the mean vector, remove the top principal components, or evaluate with rank-based metrics instead of absolute thresholds. Always compare against the empirical null distribution for your specific embedding model.
Can I use cosine similarity with k-means?
scikit-learn’s KMeans optimises squared Euclidean distance. If you L2-normalise your rows first, squared Euclidean distance becomes a monotone function of cosine similarity (‖a − b‖² = 2 − 2cos), so the assignment step agrees. The centroid update still lives in Euclidean space, however; if you want the principled version, use spherical k-means, which constrains centroids to the unit sphere.
Does the concentration of cosine similarity mean high-dimensional vectors are useless?
No. It means the null model is different. Real data in high dimensions is far from isotropic; it concentrates on low-dimensional structures, and it is those structures — not the ambient dimension — that produce meaningful similarity. The lesson is about calibration, not about abandoning the method. The failure mode is believing a similarity score without knowing what a random score would have been.
Is dot product ever preferable to cosine?
Yes, when magnitude is part of the signal. In attention mechanisms the magnitude of the query–key inner product encodes confidence in the match, and removing it would discard information. Similarly, some recommender formulations deliberately use unnormalised dot products so that item popularity enters the ranking. The mistake is not using the dot product; it is using it without knowing that this is what you chose.
Related posts:
 Data science interview preparation kit
 The Art of Python One-Liners: How Data Scientists Write Less Code to Solve More Problems
 The Data Scientist’s Blueprint: Design Patterns That Separate Amateurs From Architects
 The Unseen Architects of Reality: How Discrete Probability Distributions Govern Your Digital World
Leave a Reply